
 English
 Français
 Español
 Deutsch
 Português
 Italiano
 العربية
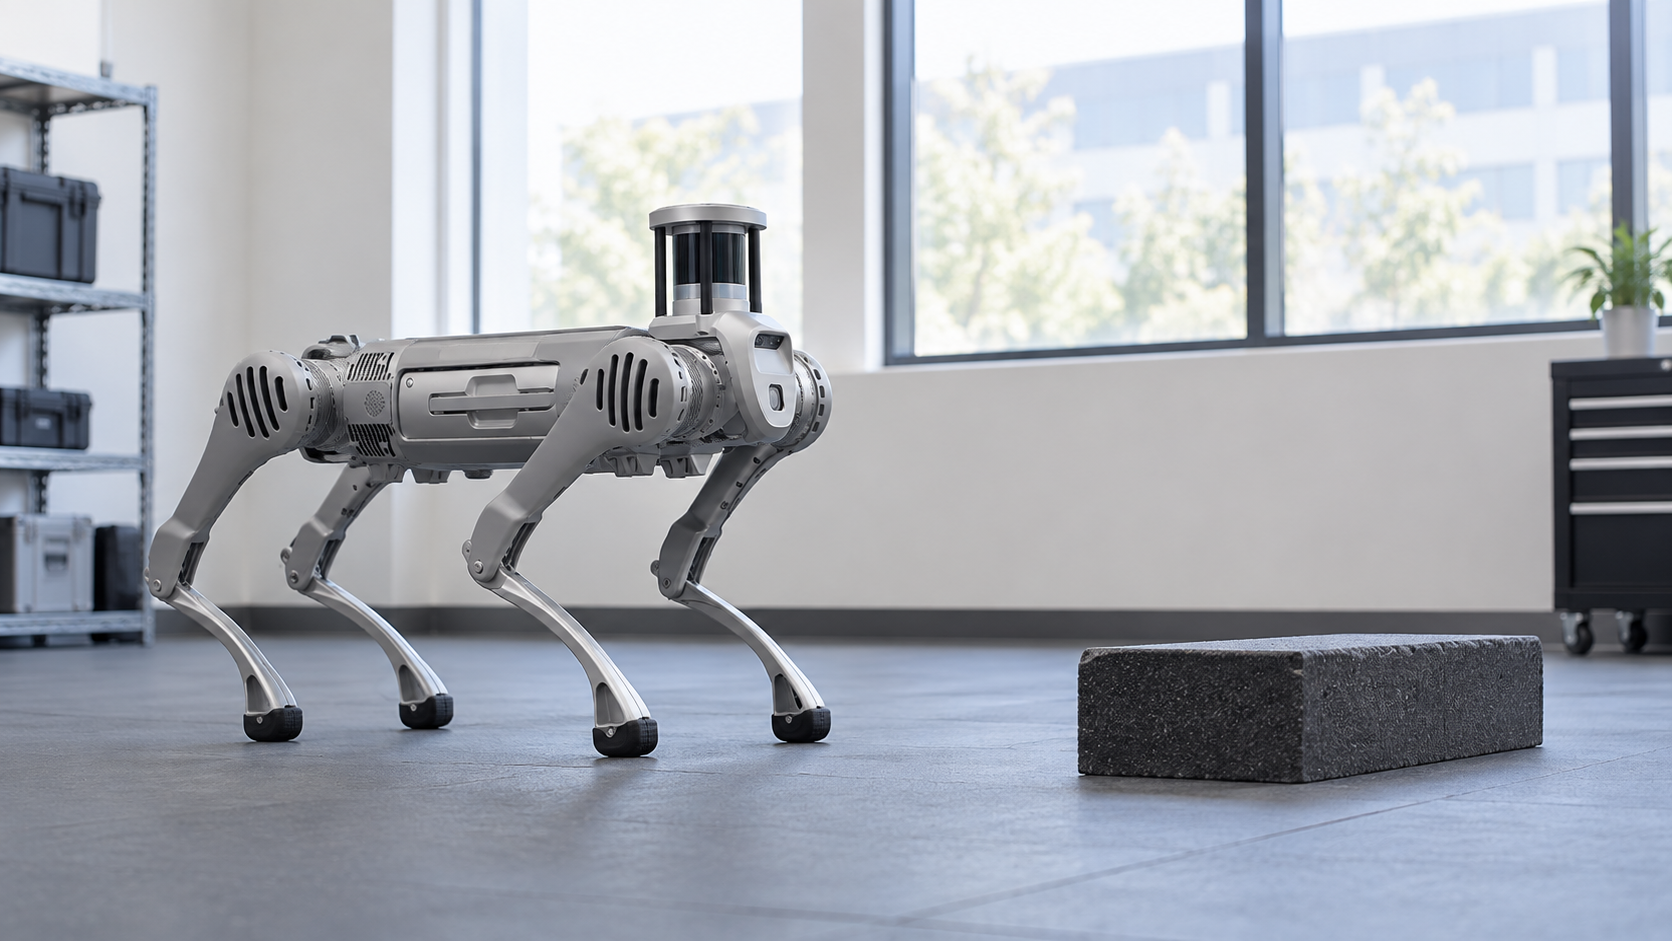
A robot can complete a task thousands of times without leaving a virtual room. That is one of the useful ideas behind Physical AI simulation: software can expose a machine's decision-making to situations that would be slow, expensive or difficult to recreate with real equipment.
But a successful virtual run leaves an important question unanswered. What, exactly, was tested? A robot moving through a simulated corridor, a 3D building showing live sensor values and an automation processing a mock response can all look like testing a digital version of reality. They establish very different things.
Understanding the difference makes the whole subject more interesting. It explains how robots can learn before they move, how a building's operational logic can be tested before it sends a command, and why neither exercise removes the need to check the physical installation. A convincing screen animation is only useful when it corresponds to the question the test is meant to answer.
Digital twin simulation: what can a virtual building actually test?
A digital representation of a building can serve several purposes. It might show where devices are installed and display their current measurements. It might model movement through the space. It might support calculations about physical behavior. The shared building shape does not mean those representations contain the same information or can answer the same questions.
A live 3D view is useful because it connects information to a place people recognize. A reported door state can appear on the corresponding door. A room's sensor readings can be associated with the room itself. That can make a large property easier to understand than a list of unfamiliar device identifiers. The value comes from locating observations, not from predicting every possible event.
A physics simulation needs more. If the question is whether a robot can travel across a surface or handle an object, geometry alone is insufficient. The model may need relevant properties of materials, contact and movement, along with suitable representations of the robot and its sensors. The required detail depends on the behavior being investigated.
There is also a workflow model: what the software does when information arrives. It can test whether a room event selects the intended branch or whether an unavailable robot produces the right operational response. That test may need device identities, timestamps and representative replies without needing realistic floor textures or a simulated robot body.
These representations can contribute to the same project, but one should not silently stand in for another. Seeing a door change color in a 3D dashboard does not prove that a robot can open it. Seeing a robot traverse a virtual room does not prove that a real mission request reaches the correct machine. Each test needs an explicit relationship to the behavior being claimed.
Robot simulation: teaching movement before the first real mission
Robot simulation provides an environment where robot software can encounter controlled situations. Depending on the tools and model, that may involve virtual cameras, objects, obstacles and movement. Developers can repeat a condition, vary it and compare behavior without rebuilding the physical scene for every attempt.
That repetition is particularly useful when learning is involved. A system trained through reinforcement learning can explore actions against a defined objective in simulation. Other workflows use demonstrations, synthetic observations or evaluation of an existing policy. These are different methods, and not every robot learns in the same way. Simulation is a tool used within a development process rather than a single recipe for intelligence.
Variation matters as much as repetition. If a robot only succeeds with one object position and one lighting condition, repeating that success does not establish much about a changing environment. Virtual scenes can expose the system to different arrangements and observations. The useful question is whether those variations represent challenges it may encounter outside the simulator.
An inspection robot provides a straightforward example. Its development environment might include corridors of different widths, obstacles in different places and changes in what its sensors observe. The software can be evaluated against those situations before a real trial. That is distinct from deciding which building event should request an inspection in the first place.
Simulation also makes some failures easier to study. A run can be repeated with the same initial conditions, helping identify which change affected the outcome. In a real building, people and equipment may move between trials. Both environments provide useful evidence, but the ability to control a virtual experiment helps isolate questions that are harder to separate in the physical world.
The simulator still reflects choices made by its developers. What is represented, simplified or omitted affects what a successful run means. A model that captures movement well may not capture a particular sensor problem. A visually detailed scene may still omit an important interaction. Realism has to be relevant to the task, not just impressive to a viewer.
Sim-to-real transfer: why a successful simulation is only the start
The sim-to-real gap is the difference between the modeled environment and the one the robot actually encounters. Surfaces, objects, lighting, sensing and timing can behave differently. Those differences matter when a learned behavior depends on details the simulator represented imperfectly or never included.
This is why simulated success is evidence with a scope. It can show that a policy or workflow handled the tested conditions in the model. It cannot establish that every relevant condition was included or that the physical installation matches the assumptions. Moving from simulation to reality is another evaluation step, not simply exporting a file and declaring the job finished.
A virtual corridor illustrates the issue. Its dimensions may match the building, yet the real route might contain reflective surfaces, a temporary obstruction or a door that behaves differently. Some differences can be added to the model. Others are discovered through controlled real-world checks. The two kinds of testing can inform each other as the project develops.
The same principle applies outside movement. A simulated device can return a response immediately, while real equipment may respond later or not at all. A network can deliver duplicate or delayed observations. A software test that always receives a clean, timely reply may prove only that the normal path works. It has not established how the system handles the installation's less convenient behavior.
For a building inspection project, the evidence therefore comes in layers. Robot testing addresses movement and observation. Integration testing addresses the mission interface and feedback. Workflow testing addresses how the event becomes a task. A real deployment needs the relevant layers to work together, rather than relying on one impressive demonstration as proof of the entire system.
Physical AI simulation: testing workflows without moving equipment
The logic around a physical task is often testable before the machine is available. A motion event, a room identifier and a mission response can be represented as inputs. Software can then evaluate whether the intended decision path is followed. This is useful even when no 3D simulator is involved.
Take the illustrative building inspection workflow. A recent event from the expected room should be handled differently from an old event whose relevance has passed. An unavailable robot should produce a different outcome from an accepted mission. A repeated report should not accidentally create work that the design intended to request only once. Those are operational questions, not questions about how the robot bends its legs.
Kilo's Physical AI platform supports this part of the development process through device emulation and rule debugging. Emulated readings provide controlled inputs for workflows. Debugging makes branches, variables and supported side effects inspectable. This tests the operation around equipment; it is not a claim that Kilo provides a physics engine for robot movement or trains robotics foundation models.
The side-effect controls need particular care. In Kilo's debugger, Execute runs the real handler and is selected initially. Skip avoids the side effect while leaving variables unchanged. Mock supplies a stand-in response so the workflow can continue. A test intended to avoid a real command therefore needs Skip or Mock chosen deliberately. Entering the debugger alone does not isolate equipment.
A mock response is a useful way to explore an outcome that may be difficult to reproduce on demand. For example, a test can supply an unavailable result and inspect how the workflow handles it. But the response needs to reflect the actual integration contract. Inventing convenient fields or statuses would test an interface that does not exist.
Suitable sensors and gateways can be sourced through Kilo Electronics when the project moves to physical equipment. That transition adds questions the emulated setup could not answer: whether the observation arrives from the actual installation, whether its timing is suitable and whether the intended device operation is supported. The test plan grows with the evidence needed, not simply with the number of devices purchased.
Physical AI testing: what mocks cannot prove
A mock can show how software handles a supplied response. It cannot show that a robot reached a room, that a sensor detects the intended event or that a radio link works through the building's walls. Those are properties of the real equipment and environment. Keeping the distinction clear prevents a successful software test from becoming an unsupported physical claim.
Even the word “success” needs context. An accepted mission request may be enough to test the next software branch, but it is not evidence of a completed inspection. The actual integration may expose later states or additional observations. Tests should represent the distinctions available in that interface rather than collapse them into one optimistic reply.
Fault scenarios are useful when they relate to a real decision. What happens if the sensor observation is too old? What if the command is rejected? What if the mission is accepted but never reports completion? The answer should describe an observable outcome and the person or system responsible for unresolved work. A model's fluent explanation is not a substitute for that behavior.
Versioning keeps the tested design connected to the released one. Kilo stores rule versions and can restore an available earlier design as a new draft. Building and deploying remain separate. The previously deployed artifact continues until another build is deployed. That makes it possible to inspect the change being released instead of assuming the latest edit is already running.
Restoration has a limit that simulation can easily obscure: physical actions do not rewind with software. A robot may already have traveled, or another device may already have changed state. Recovering earlier logic does not reverse those events. Any necessary cancellation or corrective operation depends on the equipment's actual capabilities and the installation's procedures.
The strongest test record is therefore specific. It says which inputs were used, which responses were simulated, whether any real side effects ran and which version was examined. That is more useful than a broad statement that the system was “tested in a digital twin.” It tells the next person what the evidence supports and what remains to be checked.
Physical AI simulation FAQ: digital twins, tests and real equipment
Is every digital twin a simulator?
No. A digital twin may primarily organize live information around a representation of an asset. Simulation requires models suitable for the behavior being investigated. A live building view and a physics environment can both be useful while answering different questions.
Can workflow testing replace robot simulation?
No. Workflow tests can evaluate decisions, interface handling and controlled responses. Robot simulation can address movement, sensing or learned behavior in a modeled environment. A project may need both, followed by appropriate checks with real equipment.
Does a mock make a test automatically safe?
Only the effects actually mocked are replaced. Other actions may still be real. In Kilo, supported side-effect nodes require a deliberate Execute, Skip or Mock choice, and Execute is initially selected. The relevant test boundary must be known before the run.
Why put so much effort into virtual tests?
They make it possible to inspect decisions and repeat difficult cases before relying on them in an installation. Their value grows when their limits are clear. A robot can practice movement, software can practice handling outcomes, and the real-world checks can focus on what neither model has established yet.